
Joint ecological intensity from opportunistic records
Source:vignettes/articles/gbif-joint-intensity.Rmd
gbif-joint-intensity.RmdOpportunistic occurrence records — GBIF downloads, portal submissions, atlas compilations — are plentiful exactly where people go and sparse everywhere else. This article fits a joint model to such records alone: many species, one shared ecological gradient, and an explicit, named recording-bias term. It is the presence-only opener of the species-distribution series; the integrated articles that follow show what changes when a designed survey is added to the same model.
This is the simplest model in the series: one shared ecological
gradient, one named bias term, no other data sources — an ordinary
gllvmTMB() call with no integration machinery. Everything
it estimates is relative ecological intensity: where
each species’ recorded intensity is higher or lower, after effort and
the named bias are accounted for. It does not estimate abundance,
absolute occurrence probability, or detectability, and no number below
should be read as if it did.
Why model species jointly when the data are mostly zeros?
Consider a wetland restoration programme comparing six species across a landscape of cells. A separate single-species model per taxon gives six maps, but discards a useful biological premise: species can share an unmeasured ecological gradient while keeping species-specific departures. Jointly, the sparse species borrow strength from the common gradient, and the model reports which species co-vary beyond what the measured environment explains.
For cell and species , the ecological linear predictor is
so the between-cell species covariance is with and . The rank-one term is the shared unmeasured gradient; the free diagonal keeps it from being forced to explain every species-specific deviation.
The records themselves are counts with a known effort exposure and a measured bias covariate :
The terms belong to the recording process, not to ecology: they describe each species’ association with the bias covariate (accessibility, urban proximity, observer density) beyond what the effort offset already carries. Identifying them is a design assumption, not a package guarantee — the bias covariate must vary separately enough from the environmental predictors. In the simulation below the two are independent by construction; in a real dataset you must argue this from the study design.
Simulate a six-species wetland community
Three hundred cells, six species, one portal-style record stream. Effort varies tenfold across the landscape and is treated as known (in practice: visit counts, checklist counts, or records of a reference group). The bias covariate is simulated independently of the wetland gradient — the assumption flagged above, made true here by design.
n_cell  <- 300
cells   <- paste0("cell_", seq_len(n_cell))
species <- c("sedge_wren", "rail", "bittern",
             "sundew", "sphagnum", "darner")

x <- as.numeric(scale(runif(n_cell)))             # measured wetland gradient
b <- as.numeric(scale(runif(n_cell)))             # accessibility (bias), independent of x
z <- rnorm(n_cell)                                # unmeasured shared gradient
effort <- exp(log(0.12) + 1.15 * (b - min(b)) / diff(range(b)) * 2)  # ~10x range, tracks access

alpha  <- c(-0.4,  0.1, -0.8,  0.3,  0.6, -0.2)
beta   <- c( 0.9,  0.5,  0.7,  1.1,  0.8, -0.3)   # wetland responses
lambda <- c( 0.8,  0.6,  0.7, -0.5, -0.6,  0.4)   # shared-gradient loadings
psi    <- c( 0.4,  0.3,  0.5,  0.3,  0.4,  0.3)   # species-specific residual sd
gamma  <- c( 0.6,  0.1,  0.0,  0.4,  0.2,  0.9)   # recording-bias associations

dat <- expand.grid(cell_id = cells, trait = species,
                   stringsAsFactors = FALSE)
ci <- match(dat$cell_id, cells)
si <- match(dat$trait, species)
eta <- alpha[si] + x[ci] * beta[si] + z[ci] * lambda[si] +
  rnorm(nrow(dat), 0, psi[si])
dat$value      <- rpois(nrow(dat), effort[ci] * exp(eta + b[ci] * gamma[si]))
dat$trait      <- factor(dat$trait, levels = species)
dat$cell_id    <- factor(dat$cell_id)
dat$env        <- x[ci]
dat$access     <- b[ci]
dat$log_effort <- log(effort[ci])
mean(dat$value == 0)
#> [1] 0.5933333
Most cells hold zero records for most species — the familiar shape of opportunistic data.
One ordinary fit
Every piece of the model above maps onto the standard long-format
grammar: per-species intercepts and slopes as trait
interactions, the known effort as an offset, and the shared gradient as
a rank-one latent() term (which carries its diagonal
companion by default):
fit <- gllvmTMB(
  value ~ 0 + trait + trait:env + trait:access + offset(log_effort) +
    latent(0 + trait | cell_id, d = 1),
  data   = dat,
  trait  = "trait",
  unit   = "cell_id",
  family = poisson(),
  silent = TRUE
)
#> Warning: ! Ordinary `latent()` now includes a per-trait Psi by default (Sigma = Lambda
#>   Lambda^T + Psi).
#> ℹ This changed in gllvmTMB 0.2.0; earlier `latent()` was loadings-only (Lambda
#>   Lambda^T).
#> → Pass `latent(..., unique = FALSE)` for the old rotation-invariant
#>   loadings-only fit.
fit$opt$convergence
#> [1] 0
0 means the optimizer reached a point it judges
stationary; run the package’s own health check rather than stopping
there:
health <- check_gllvmTMB(fit)
health[health$component %in% c("optimizer_convergence", "pd_hessian"),
       c("component", "status")]
#>               component status
#> 1 optimizer_convergence   PASS
#> 4            pd_hessian   PASS
Both read PASS here: the optimizer settled, and the
curvature at that point (pd_hessian — whether the Hessian
is positive-definite, the condition that licenses standard errors) is
well-behaved. See Can I trust this
fit? for the full battery.
Does it recover what it claims to estimate?
Two claims are on the table: the per-species environmental responses , and the per-species recording-bias associations . Both are single-draw illustrations — the spread you see is sampling noise at this design size, not bias.
est_beta <- unname(fit$opt$par[grep(":env", fit$X_fix_names)])
plot(beta, est_beta, pch = 19, cex = 1.3, asp = 1,
     xlim = range(c(beta, est_beta)) + c(-0.15, 0.15),
     ylim = range(c(beta, est_beta)) + c(-0.15, 0.15),
     xlab = "true wetland-gradient slope",
     ylab = "estimated")
abline(0, 1, lty = 2)
lab_pos <- c(3, 3, 1, 3, 1, 3)   # alternate above/below to avoid collisions
text(beta, est_beta, labels = species, pos = lab_pos, cex = 0.8)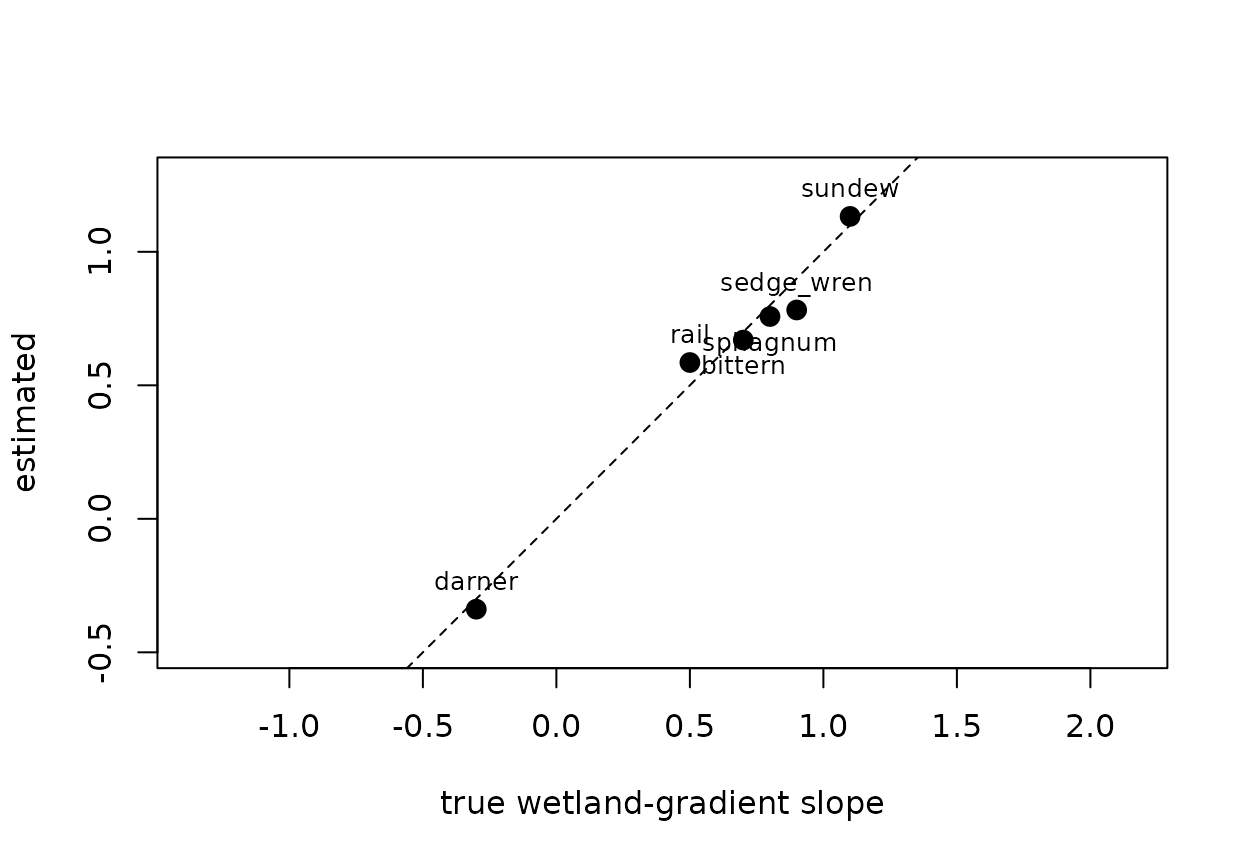
Per-species wetland-gradient slopes, simulated truth against estimate, from one fit on one simulated draw.
est_gamma <- unname(fit$opt$par[grep(":access", fit$X_fix_names)])
plot(gamma, est_gamma, pch = 19, cex = 1.3, asp = 1,
     xlim = range(c(gamma, est_gamma)) + c(-0.15, 0.15),
     ylim = range(c(gamma, est_gamma)) + c(-0.15, 0.15),
     xlab = "true recording-bias association",
     ylab = "estimated")
abline(0, 1, lty = 2)
lab_pos <- c(3, 3, 1, 3, 1, 3)
text(gamma, est_gamma, labels = species, pos = lab_pos, cex = 0.8)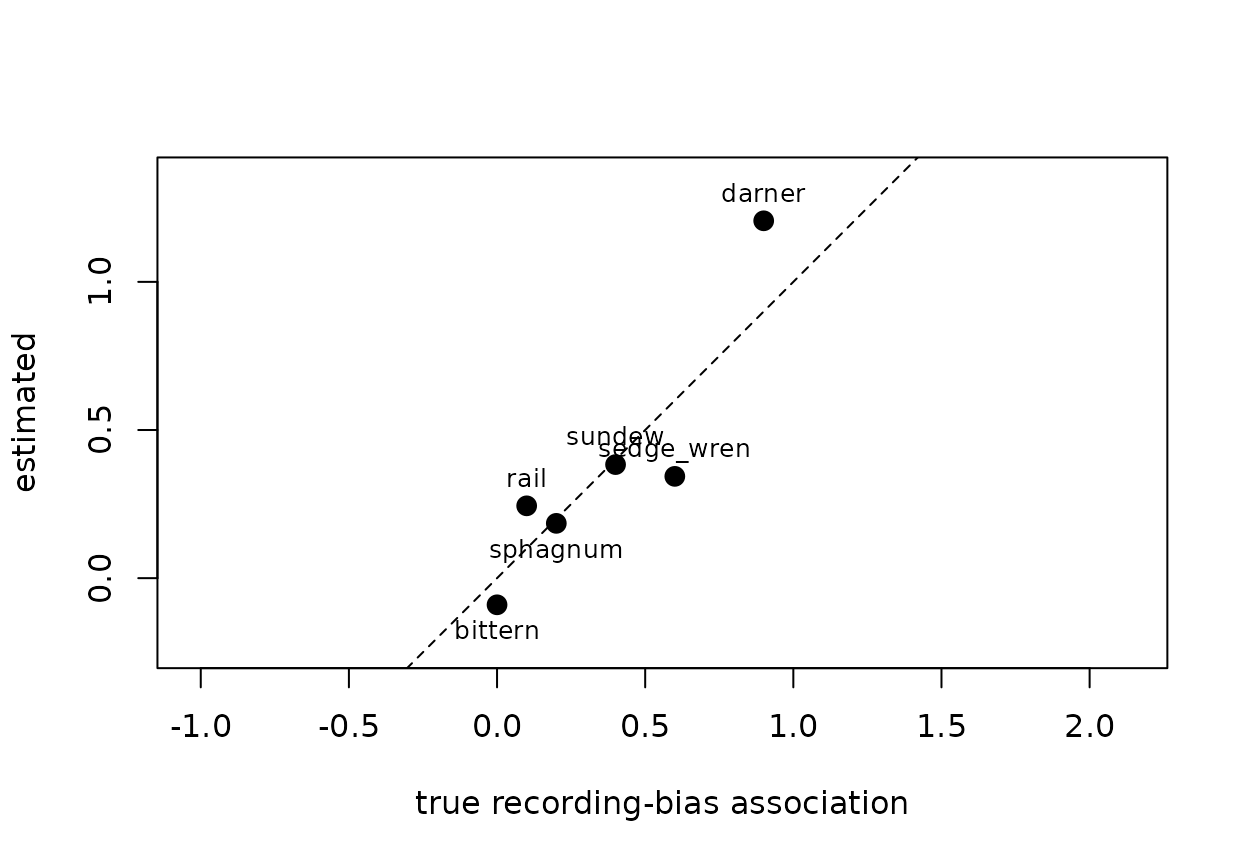
Per-species recording-bias associations, simulated truth against estimate, from the same single fit on one simulated draw. These are recording-process quantities, not ecology; their identification rests on the bias covariate varying separately from the environmental predictors.
The two panels are not equally tight, and the difference is instructive. The ecological slopes recover closely. The recording-bias associations scatter more — they are informed only by how record counts co-vary with accessibility after effort, a weaker signal at this record density. That pattern is a reasonable expectation for models like this, not a guarantee from one draw. Because the bias associations are estimated jointly with the ecology, a species recorded mostly near roads is still not mistaken for a species that prefers whatever habitat roads run through — provided, again, that roads and habitat vary separately.
The joint part: residual co-occurrence
The quantity a stack of single-species models cannot give you is the between-cell species correlation after environment, effort, and bias are accounted for — the rotation-invariant summary of :
corr_rows <- extract_correlations(
  fit,
  tier = "unit",
  method = "fisher-z",
  link_residual = "auto"
)
head(corr_rows[order(-abs(corr_rows$correlation)), ], 5)
#>    tier    trait_i  trait_j correlation      lower      upper   method
#> 10    B     sundew sphagnum   0.4528213  0.3579346  0.5384515 fisher-z
#> 8     B       rail sphagnum  -0.3432571 -0.4394174 -0.2393187 fisher-z
#> 5     B       rail   sundew  -0.3425334 -0.4387555 -0.2385455 fisher-z
#> 7     B sedge_wren sphagnum  -0.3386130 -0.4351674 -0.2343586 fisher-z
#> 4     B sedge_wren   sundew  -0.3378991 -0.4345138 -0.2335966 fisher-z
#>          interval_status
#> 10 heuristic_unvalidated
#> 8  heuristic_unvalidated
#> 5  heuristic_unvalidated
#> 7  heuristic_unvalidated
#> 4  heuristic_unvalidated
The lower/upper bounds and the
interval_status column are Fisher-z heuristics, and the fit
reports them as exactly that — heuristic_unvalidated.
Calibrated coverage for this route has not been established; read the
bounds as descriptive spread, not as a coverage guarantee.
The point estimates recover the block structure written into : the two plants load together (the strongest printed pair), and every printed bird–plant pair is negative, matching their opposite-signed loadings. In a real analysis these correlations are descriptions of residual co-occurrence, not causal interaction claims.
What this model cannot tell you
Everything above is relative intensity, and the boundary is worth stating precisely:
- No absolute quantities. Abundance, occupancy probability, and detectability are all inaccessible from opportunistic records alone, because the recording process and the ecological process enter the intensity multiplicatively and only their product is observed.
- The effort offset is assumed known. If is itself estimated or mis-specified, its error moves directly into the intercepts and, when correlated with covariates, into the slopes.
- Bias identification is a design property. When the bias covariate tracks the environment, and are confounded and no fitting choice can separate them.
The way past each of these limits is more data of a different kind, not more records of the same kind. Adding even a small designed survey — detection/non-detection with known effort — anchors the recording levels and is exactly what the integrated route provides:
See also
- Integrating opportunistic records with a designed survey — the two-source integrated model this article’s fences point toward.
- How big does an integrated survey design need to be?
- More than two sources
- Joint species distribution model — the binary-occurrence JSDM guide, without the point-process framing.
References
Blanchet, F.G., Cazelles, K. and Gravel, D. (2020). Co-occurrence is not evidence of ecological interactions. Ecology Letters 23, 1050–1063.
Elith, J., Graham, C.H., Anderson, R.P., et al. (2006). Novel methods improve prediction of species’ distributions from occurrence data. Ecography 29, 129–151.
Renner, I.W., Elith, J., Baddeley, A., Fithian, W., Hastie, T., Phillips, S.J., Popovic, G. and Warton, D.I. (2015). Point process models for presence-only analysis. Methods in Ecology and Evolution 6, 366–379. https://doi.org/10.1111/2041-210X.12352
Warton, D.I., Renner, I.W. and Ramp, D. (2013). Model-based control of observer bias for the analysis of presence-only data in ecology. PLoS ONE 8, e79168. https://doi.org/10.1371/journal.pone.0079168
Warton, D.I., Blanchet, F.G., O’Hara, R.B., Ovaskainen, O., Taskinen, S., Walker, S.C. and Hui, F.K.C. (2015). So many variables: joint modeling in community ecology. Trends in Ecology & Evolution 30, 766–779.
Zurell, D., Pollock, L.J. and Thuiller, W. (2018). Do joint species distribution models reliably detect interspecific interactions from co-occurrence data in homogenous environments? Ecography 41, 1812–1819.