
When a rare species breaks the JSDM
Source:vignettes/articles/rare-species-jsdm.Rmd
rare-species-jsdm.RmdThe species that break a joint species distribution model are usually the ones you care about most. A rare specialist — recorded only at the warmest sites, only above the treeline, only in the oldest forest — gives the fixed-effect design a pattern a straight line can split perfectly, and at that point its maximum-likelihood coefficient has no finite value. The bad responses are to delete the species quietly, or to publish whatever number the optimizer happened to stop at. This page shows the packaged response: certify the problem, then keep the species with an estimator whose behaviour at the boundary is explicit.
The estimator (estimator = "mspl") is opt-in and
experimental; ordinary maximum likelihood stays the default, and nothing
switches automatically. This page is the species-facing door to that
machinery — the evidence-synthesis
article walks the same tools through their full paces (including the
other failure mode, runaway latent loadings, and its different
remedy).
A butterfly guild with one heat specialist
Ninety sites along a temperature gradient, six butterflies. Five are ordinary; the sixth is present only at the very warmest sites — the threshold pattern real specialists actually show.
library(gllvmTMB)

set.seed(88)
n_site <- 90
species <- c("meadow_brown", "common_blue", "small_heath",
             "grayling", "wall_brown", "silver_studded")
temp <- as.numeric(scale(seq_len(n_site)))
z   <- matrix(rnorm(n_site * 2), n_site, 2)   # two latent site axes
Lam <- matrix(rnorm(12, 0, 0.9), 6, 2)
alpha <- c(0.6, 0.2, 0.4, -0.5, 0.0, -2.4)
beta  <- c(0.3, -0.4, 0.5, 0.8, -0.2, 1.0)

eta <- sweep(z %*% t(Lam), 2, alpha, "+") + outer(temp, beta)
Y <- matrix(rbinom(n_site * 6, 1, plogis(eta)), n_site, 6,
            dimnames = list(NULL, species))
Y[, "silver_studded"] <- as.integer(temp > quantile(temp, 0.92))
sites <- data.frame(site = factor(seq_len(n_site)), temp = temp, Y)
round(colMeans(Y), 2)
#>   meadow_brown    common_blue    small_heath       grayling     wall_brown
#>           0.64           0.58           0.58           0.34           0.52
#> silver_studded
#>           0.09
Note what makes this dangerous: the problem is not rarity itself. A
species at 8% prevalence scattered across the gradient fits fine. This
one’s presences all sit past a temperature threshold, so a line on
temp can separate every presence from every absence — and
that is a property of the fixed design, diagnosable before any model is
fitted. The same certificate fires for a species present at almost every
site: rarity is not the definition of the problem; a perfect split
is.
Certify the problem before fitting
screen_gllvmTMB() runs the formal separation test
species by species (it uses the optional detectseparation
package):
scr <- screen_gllvmTMB(
  traits(meadow_brown, common_blue, small_heath,
         grayling, wall_brown, silver_studded) ~ 1 + temp,
  data = sites, unit = "site", family = binomial(),
  control = screen_control(separation = "fixed")
)
screen_table(scr, "separation")[, c("traits", "status", "severity",
                                    "separated", "infinite_terms")]
#> Install the optional detectseparation package to run this certificate.Five species pass with overlap; the silver-studded is
flagged complete, and infinite_terms names
exactly which of its coefficients have no finite maximum-likelihood
estimate. The screen only diagnoses — it never chooses an estimator for
you.
What happens if you fit anyway
The long-format JSDM call is the same one the JSDM guide uses; traits() wide
form fits the identical model.
long <- data.frame(
  site  = rep(sites$site, times = 6),
  trait = factor(rep(species, each = n_site), levels = species),
  temp  = rep(sites$temp, times = 6),
  value = as.vector(Y)
)

form <- value ~ 0 + trait + trait:temp +
  latent(1 | site, d = 2, unique = FALSE)
fit_ml <- tryCatch(
  suppressWarnings(gllvmTMB(
    form, data = long, unit = "site", trait = "trait",
    family = binomial(), estimator = "ml",
    control = gllvmTMBcontrol(n_init = 1, se = FALSE, warn_runaway = FALSE)
  )),
  error = identity
)
if (inherits(fit_ml, "error")) {
  cat("ML did not return a fitted point:\n", conditionMessage(fit_ml), "\n")
} else {
  co <- coef(fit_ml)
  cat("ML slope for the separated species:",
      round(unname(co[grep("silver_studded:temp", names(co))]), 1), "\n")
}
#> ML did not return a fitted point:
#>  All 1 restarts failed.
On this draw ordinary maximum likelihood fails to return a usable fit at all; on other draws the same disease shows up differently — the optimizer “converges” with an absurd slope instead. Either way, the certificate above already told you no finite ML estimate exists for those terms; whatever number does come back for them is an artefact of where the optimizer stopped, not an estimate.
Keep the species with MSPL
fit_mspl <- suppressWarnings(gllvmTMB(
  form, data = long, unit = "site", trait = "trait",
  family = binomial(), estimator = "mspl",
  control = gllvmTMBcontrol(n_init = 1, se = FALSE)
))
fit_mspl$opt$convergence
#> [1] 0
MSPL adds a sample-size-scaled Jeffreys-prior penalty on the fixed design (Kosmidis & Firth 2021; Sterzinger & Kosmidis 2023), which guarantees the separated coefficients a finite maximum. The species stays in the model, and its fitted relationship to temperature becomes a curve you can actually plot — steep, as the data demand, but finite:
pred <- predict(fit_mspl, type = "response", re_form = ~ 0)
idx <- long$trait == "silver_studded"
ord <- order(long$temp[idx])
plot(long$temp[idx][ord], pred$est[idx][ord], type = "l", lwd = 2,
     xlab = "temperature (scaled)", ylab = "occurrence probability",
     ylim = c(0, 1))
points(long$temp[idx], long$value[idx], pch = 3, cex = 0.7)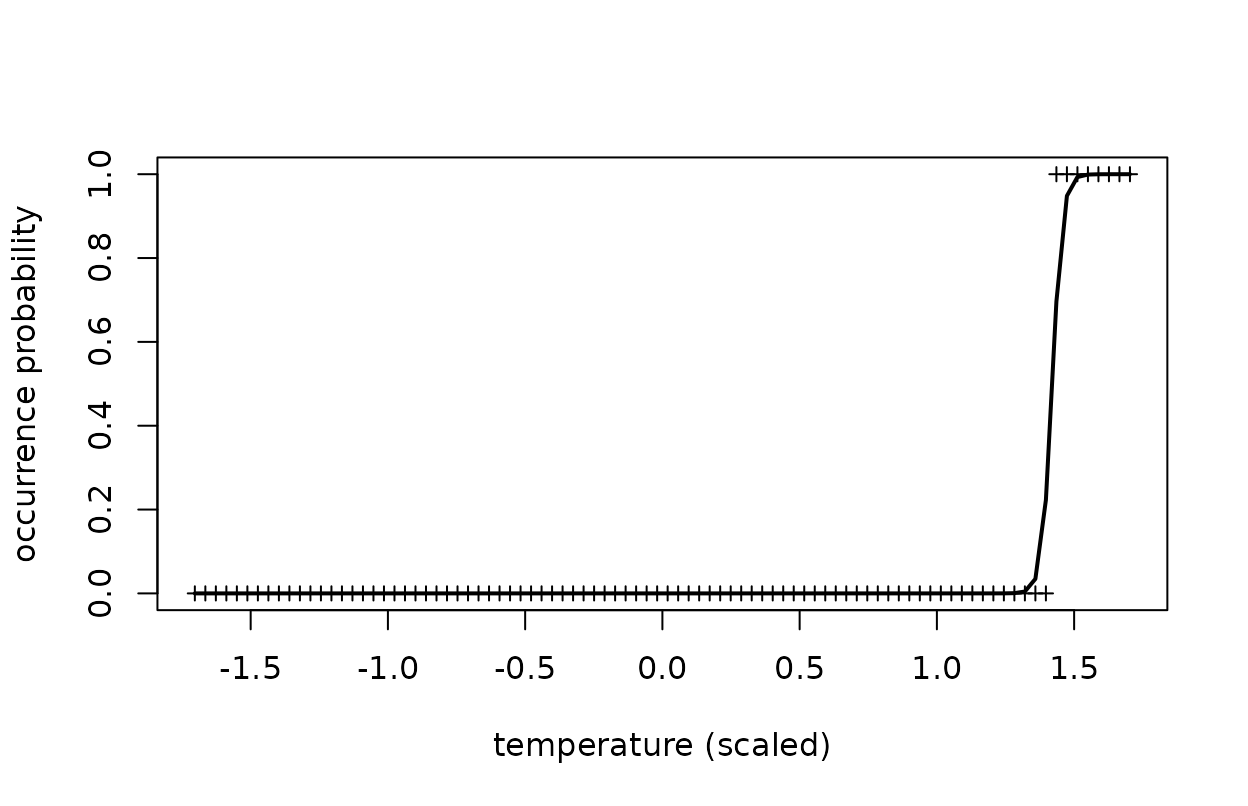
Fitted occurrence probability for the separated heat specialist under MSPL, on the response scale with the site-level latent scores excluded. The curve is a penalised point estimate: finite and reportable, with no uncertainty band because interval methods are deliberately withheld for this estimator.
Why not the loading ridge?
The package’s other opt-in stabiliser,
gllvmTMBcontrol(loading_ridge = 2), is sometimes reached
for here — and it is the wrong tool for this disease. It penalises the
latent loadings; separation lives in the fixed
effects:
fit_ridge <- tryCatch(
  suppressWarnings(gllvmTMB(
    form, data = long, unit = "site", trait = "trait",
    family = binomial(), estimator = "ml",
    control = gllvmTMBcontrol(n_init = 1, se = FALSE, warn_runaway = FALSE,
                              loading_ridge = 2)
  )),
  error = identity
)
if (inherits(fit_ridge, "error")) {
  cat("Ridge fit did not return a fitted point.\n")
} else {
  co <- coef(fit_ridge)
  cat("convergence:", fit_ridge$opt$convergence,
      "| slope for the separated species:",
      round(unname(co[grep("silver_studded:temp", names(co))]), 1), "\n")
}
#> convergence: 1 | slope for the separated species: 227.3
The separated species’ slope is still runaway — the ridge changed
nothing about the boundary the certificate diagnosed. And the two
remedies must not be stacked: supplying loading_ridge
together with estimator = "mspl" is refused with an error.
One outer penalty per fit — the ridge shrinks loadings, and this
species’ boundary is in the fixed-effect slope. The ridge’s own job —
taming runaway loadings — is demonstrated in the evidence-synthesis article.
What the penalised fit does and does not give you
It gives you a finite, reportable point estimate for every coefficient, a species kept in the joint model rather than silently dropped, and a defensible sentence for the paper: “the species’ occurrence rises sharply past the temperature threshold; its coefficient is a penalised point estimate because the design shows complete separation.”
It does not give you ordinary inference.
logLik(), AIC/BIC, likelihood-ratio comparisons against the
ML fit, standard errors, and confidence intervals all fail with a typed
error rather than returning uncalibrated numbers — repeated-sampling
calibration for this estimator is still in progress. And the penalised
point is not evidence that the separation disappeared: the certificate’s
verdict about the data still stands. Report the certificate
together with the estimate.
If your fit shows the other classic pathology — convergence with latent loadings at absurd magnitudes — that is a different disease with a different remedy (an opt-in loading ridge), and the evidence-synthesis article demonstrates each remedy against its own disease — one outer penalty per fit, never both.
See also
- Joint species distribution model — the JSDM this page’s workflow protects.
- Screen binary traits before fitting — the wider pre-fit screening workflow.
- Rare items and runaway estimates in Paper × Items evidence synthesis — the same estimator in full, with the ridge comparison and all fences.
References
- Kosmidis I, Firth D (2021). Jeffreys-prior penalty, finiteness and shrinkage in binomial-response generalized linear models. Biometrika 108:71–82. https://doi.org/10.1093/biomet/asaa052
- Sterzinger P, Kosmidis I (2023). Maximum softly-penalized likelihood for mixed effects logistic regression. Statistics and Computing 33:53. https://doi.org/10.1007/s11222-023-10217-3