
What do repeated survey visits add to an integrated model?
Source:vignettes/articles/integrated-repeated-visits.Rmd
integrated-repeated-visits.RmdExperimental. The model here is fitted through the ordinary
gllvmTMB()entry point with theisdm_sources()declaration — the same experimental route as its sibling articles: the interface may change without deprecation, and no released capability claim is made. The example exists so that early users can see what visit structure adds, end to end, on simulated data.
A designed survey earns its keep twice. The two-source article showed the first half: detection/non-detection with known effort anchors the recording levels that presence-only records cannot anchor. This article shows the second half: repeated visits at the same cells, under conditions that vary between visits, let the model tell a poor visit apart from genuinely low ecological intensity. A single zero is ambiguous — the species may not have been there, or the visit may have been short, wet, or badly timed. Replication under varying conditions is what resolves the ambiguity, and it is a property of the survey design, not of any fitting trick.
Everything here stays inside the integrated route’s standing boundary: relative ecological intensity — no abundance, no absolute occurrence probability, and (as the last section makes precise) no free-standing detectability parameter either.
How a visit condition enters the admitted model
Every survey visit in the integrated route is a complementary-log-log thinning of the same shared intensity. For cell , species and visit with known support and a measured visit condition (observer-hours, weather, time of day):
with the same ecological predictor every source shares. The visit-condition effects act on the log-intensity scale: a bad visit scales down the effective intensity the visit gets to thin, exactly as a smaller support would. This is the “abundance-induced detection” view of Royle & Nichols (2003) — detection improves with intensity, and visit conditions shift the rate, not a separate coin-flip.
Two things follow. First, no new interface is needed:
is an ordinary covariate column, set to its measured value on survey
rows and to zero on portal rows, so trait:cond terms are
survey-only by construction — the same source-gating device the
two-source article uses for the portal’s bias covariate. Second, this is
not the classical occupancy factorisation
with a separate logit detection process (MacKenzie et al.
2002). That model is deliberately outside the admitted set: a logit
detection arm breaks the thinned-Poisson coherence that lets all sources
share one intensity, which is why isdm_sources() refuses
logit detection declarations at the door. The last section returns to
what that boundary costs and buys.
Simulate: a portal stream plus four visits under varying conditions
Six wetland species over 250 cells. The portal stream is the familiar biased count channel. The survey visits each cell four times; each visit has its own condition , simulated independently of the wetland gradient — the same design assumption the GBIF-only article flags for its bias covariate, and it binds here identically.
n_cell  <- 250
n_visit <- 4
cells   <- paste0("cell_", seq_len(n_cell))
species <- c("sedge_wren", "rail", "bittern",
             "sundew", "sphagnum", "darner")

x <- as.numeric(scale(runif(n_cell)))    # wetland gradient (ecology)
b <- as.numeric(scale(runif(n_cell)))    # accessibility (portal bias)
z <- rnorm(n_cell)                       # unmeasured shared gradient

alpha  <- c(-0.4,  0.1, -0.8,  0.3,  0.6, -0.2)
beta   <- c( 0.9,  0.5,  0.7,  1.1,  0.8, -0.3)   # ecology
lambda <- c( 0.8,  0.6,  0.7, -0.5, -0.6,  0.4)
gamma  <- c( 0.6,  0.1,  0.0,  0.4,  0.2,  0.9)   # portal bias
delta  <- c( 0.7, -0.5,  0.3,  0.6, -0.4,  0.5)   # visit conditions

a_g <- 2.0 * exp(0.3 * b)                # portal effort tracks access
a_s <- 0.8                               # per-visit survey support

base <- expand.grid(cell_id = cells, trait = species,
                    stringsAsFactors = FALSE)
ci <- match(base$cell_id, cells)
si <- match(base$trait, species)
eta <- alpha[si] + x[ci] * beta[si] + z[ci] * lambda[si]

portal <- transform(base, isdm_source = "gbif", support = a_g[ci],
  value  = rpois(nrow(base), a_g[ci] * exp(eta + b[ci] * gamma[si])),
  env    = x[ci], access = b[ci], cond = 0, visit = NA_integer_)

visits <- do.call(rbind, lapply(seq_len(n_visit), function(v) {
  w <- rnorm(n_cell)                     # this visit's conditions, per cell
  transform(base, isdm_source = "survey", support = a_s,
    value  = rbinom(nrow(base), 1,
      -expm1(-a_s * exp(eta + w[ci] * delta[si]))),
    env    = x[ci], access = 0, cond = w[ci], visit = v)
}))

dat <- rbind(portal, visits)
dat$trait       <- factor(dat$trait, levels = species)
dat$cell_id     <- factor(dat$cell_id)
dat$log_support <- log(dat$support)
table(dat$isdm_source) / length(species)
#>
#>   gbif survey
#>    250   1000
Note the gating columns: access is the measured
accessibility on portal rows and zero on survey rows; cond
is the measured visit condition on survey rows and zero on portal rows.
Each source keeps its own observation covariates without any new
syntax.
One fit, three kinds of coefficient
fit <- gllvmTMB(
  value ~ 0 + trait + trait:env + trait:access + trait:cond +
    offset(log_support) + latent(0 + trait | cell_id, d = 1),
  data   = dat,
  trait  = "trait",
  unit   = "cell_id",
  family = isdm_sources(gbif = poisson(), survey = binomial("cloglog")),
  silent = TRUE
)
fit$opt$convergence
#> [1] 0
health <- check_gllvmTMB(fit)
health[health$component %in% c("optimizer_convergence", "pd_hessian"),
       c("component", "status")]
#>               component status
#> 1 optimizer_convergence   PASS
#> 4            pd_hessian   PASS
Both read PASS on this fit: the optimizer settled, and
the curvature at that point is trustworthy (pd_hessian —
whether the Hessian is positive-definite; the two-source article walks
through what a WARN there means).
The formula now carries three interaction families with three
different meanings, and reading them apart is the whole skill of this
model class: trait:env is ecology (shared
by every source), trait:access is the portal’s
recording process, and trait:cond is the
survey’s visit process. One fit, and each coefficient
belongs to exactly one of the three.
op <- par(mfrow = c(1, 3), mar = c(4, 4, 2, 1))
panel <- function(truth, est, label) {
  lim <- range(c(truth, est)) + c(-0.2, 0.2)
  plot(truth, est, pch = 19, cex = 1.2, asp = 1, xlim = lim, ylim = lim,
       xlab = paste("true", label), ylab = "estimated", main = label)
  abline(0, 1, lty = 2)
  text(truth, est, labels = abbreviate(species, 6),
       pos = rep(c(3, 1), 3), cex = 0.65)
}
panel(beta,  unname(fit$opt$par[grep(":env",    fit$X_fix_names)]), "ecology")
panel(gamma, unname(fit$opt$par[grep(":access", fit$X_fix_names)]), "portal bias")
panel(delta, unname(fit$opt$par[grep(":cond",   fit$X_fix_names)]), "visit conditions")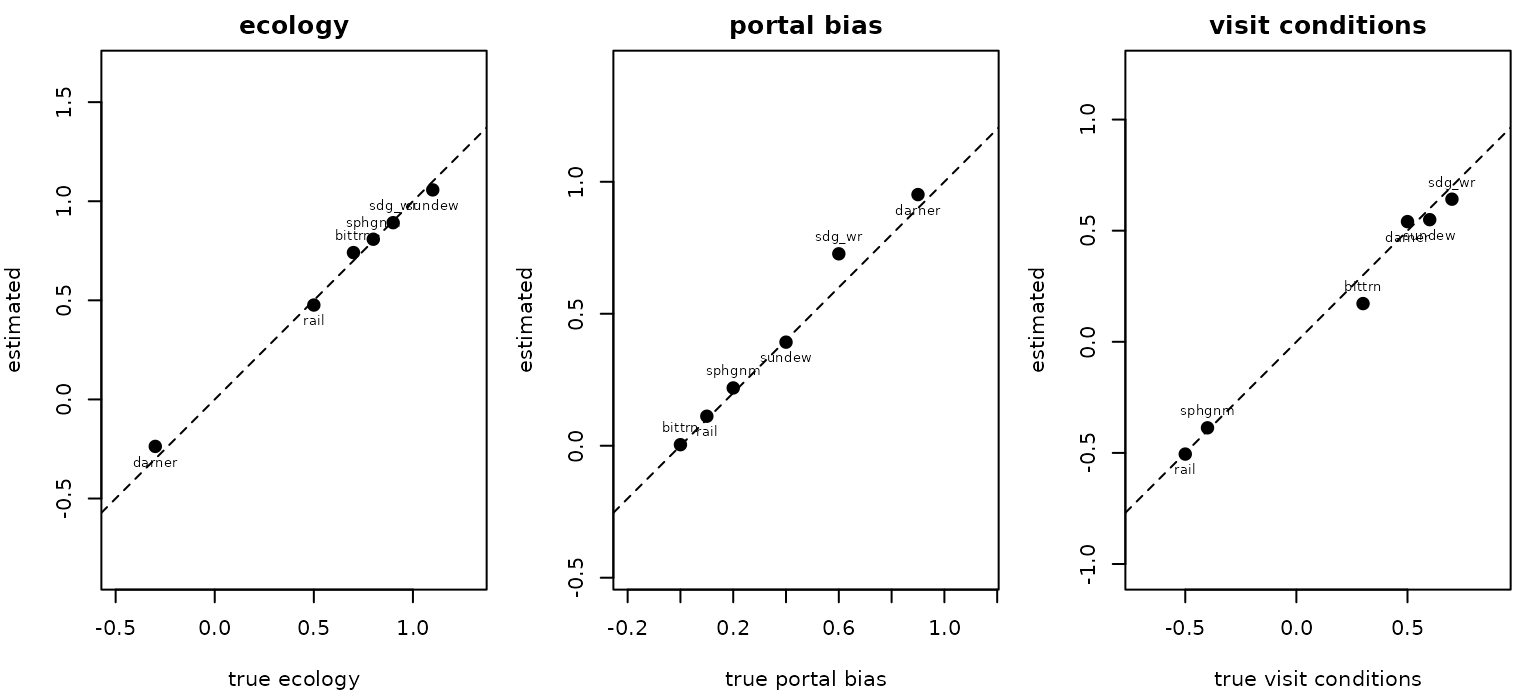
Truth against estimate for the three coefficient families — ecology (shared), portal bias (portal rows only), and visit conditions (survey rows only). One fit on one simulated draw; spread is sampling noise at this design size.
par(op)All three families recover along the identity line on this draw. The
point is not the precision of any single panel — it is that the three
processes were separable at all, and that separation came from
the design: the visit conditions varied between visits at the same
cells, and varied independently of the wetland gradient. The portal-bias
panel leans on the same requirement from the other side —
access varies independently of env in this
simulation, and its recovery depends on that just as it did in the presence-only opener.
Replication is the ingredient, not the visit count
What actually breaks when replication is removed? Refit the same model keeping only each cell’s first visit — same number of survey cells, same condition covariate, no within-cell replication:
dat1 <- rbind(portal, subset(visits, visit == 1L))
dat1$trait       <- factor(dat1$trait, levels = species)
dat1$cell_id     <- factor(dat1$cell_id)
dat1$log_support <- log(dat1$support)

fit1 <- gllvmTMB(
  value ~ 0 + trait + trait:env + trait:access + trait:cond +
    offset(log_support) + latent(0 + trait | cell_id, d = 1),
  data   = dat1,
  trait  = "trait",
  unit   = "cell_id",
  family = isdm_sources(gbif = poisson(), survey = binomial("cloglog")),
  silent = TRUE
)
round(rbind(
  truth        = delta,
  four_visits  = unname(fit$opt$par[grep(":cond",  fit$X_fix_names)]),
  one_visit    = unname(fit1$opt$par[grep(":cond", fit1$X_fix_names)])
), 2)
#>             [,1]  [,2] [,3] [,4]  [,5] [,6]
#> truth       0.70 -0.50 0.30 0.60 -0.40 0.50
#> four_visits 0.64 -0.51 0.17 0.55 -0.39 0.54
#> one_visit   0.60 -0.43 0.22 0.46 -0.28 0.75
With one visit per cell the model still runs — nothing refuses it — but on this draw the visit-condition estimates degrade visibly: each cell now contributes a single Bernoulli draw whose condition effect must be told apart from that cell’s latent ecological state using cross-cell contrast alone. The structural argument says this is no accident: repeated visits at the same cells, with at least one condition that varies by visit rather than only by cell, are what buy the separation, and the visit count matters only through the replication it provides. The comparison above is a one-draw illustration of that argument, not a measured design curve — the design article shows what a measured curve looks like for the cell-count question.
The boundary: detection through intensity, not beside it
The admitted model ties detection to intensity by construction — a species is seen more often where its intensity is higher, and visit conditions scale that rate. What it does not provide is a free-standing detectability parameter per species. If a species is simply hard to see — cryptic colouration, calls that are easy to miss — that shortfall is folded into its recording-level and intercept terms rather than estimated on its own. And its ecological map stays accurate only if the shortfall is roughly constant from cell to cell; if detectability itself varies with habitat, this model cannot separate that from real ecological change.
If your scientific question is about detectability itself — “what
fraction of occupied cells does one visit find?” — you want the
occupancy factorisation
with its own detection submodel (MacKenzie et al. 2002;
Guillera-Arroita 2017), which is a different estimand and a different
likelihood, and is refused at the isdm_sources() door
rather than half-supported. If your question is where relative intensity
is high and how sources and visits distort your view of it, the route
shown here answers it inside one coherent likelihood.
What this route does and does not cover
Covered here: repeated survey visits as additional cloglog rows sharing one intensity; per-visit support offsets; visit-condition effects via an ordinary gated interaction; recovery of ecology, portal-bias, and visit-condition coefficients illustrated on one known-truth draw.
Works but not certified: the estimates themselves — one draw, one design size, nonspatial, balanced visits.
Not available: a separate logit detection process; per-species detectability at fixed intensity; abundance or absolute occupancy from any number of visits; and calibrated confidence intervals for this route.
See also
- Integrating opportunistic records with a designed survey — the two-source model this article extends with visit structure.
- How big does an integrated survey design need to be?
- More than two sources
- Joint ecological intensity from opportunistic records — the presence-only opener, where the gating device is introduced.
References
Guillera-Arroita, G. (2017). Modelling of species distributions, range dynamics and communities under imperfect detection: advances, challenges and opportunities. Ecography 40, 281–295. https://doi.org/10.1111/ecog.02445
Isaac, N.J.B., Jarzyna, M.A., Keil, P., et al. (2020). Data integration for large-scale models of species distributions. Trends in Ecology & Evolution 35, 56–67. https://doi.org/10.1016/j.tree.2019.08.006
MacKenzie, D.I., Nichols, J.D., Lachman, G.B., Droege, S., Royle, J.A. and Langtimm, C.A. (2002). Estimating site occupancy rates when detection probabilities are less than one. Ecology 83, 2248–2255.
Miller, D.A.W., Pacifici, K., Sanderlin, J.S. and Reich, B.J. (2019). The recent past and promising future for data integration methods to estimate species’ distributions. Methods in Ecology and Evolution 10, 22–37. https://doi.org/10.1111/2041-210X.13110
Royle, J.A. and Nichols, J.D. (2003). Estimating abundance from repeated presence–absence data or point counts. Ecology 84, 777–790.